Acta Aeronautica et Astronautica Sinica ›› 2026, Vol. 47 ›› Issue (15): 333148.doi: 10.7527/S1000-6893.2026.33148
• Electronics and Electrical Engineering and Control • Previous Articles
Dian SHAO1,2,3( ), Chu TANG1,2,3, Min CHANG1,2,3, Like LIU4, Yule WANG1,2,3, Hao LI2,5, Junqiang BAI1,2,3
Received:2025-11-27
Revised:2026-01-04
Accepted:2026-02-04
Online:2026-02-28
Published:2026-02-27
Contact:
Dian SHAO
E-mail:shaodian@nwpu.edu.cn
Supported by:CLC Number:
Dian SHAO, Chu TANG, Min CHANG, Like LIU, Yule WANG, Hao LI, Junqiang BAI. Large foundation models empowering ummannod aerial vehicle intelligence: Progress, applications and perspectives[J]. Acta Aeronautica et Astronautica Sinica, 2026, 47(15): 333148.
Fig.1
Panorama of Large Foundation Models (LFMs) empowering UAV intelligence: Model foundations, functional reshaping (basic and high-order), typical tasks, challenges and prospects
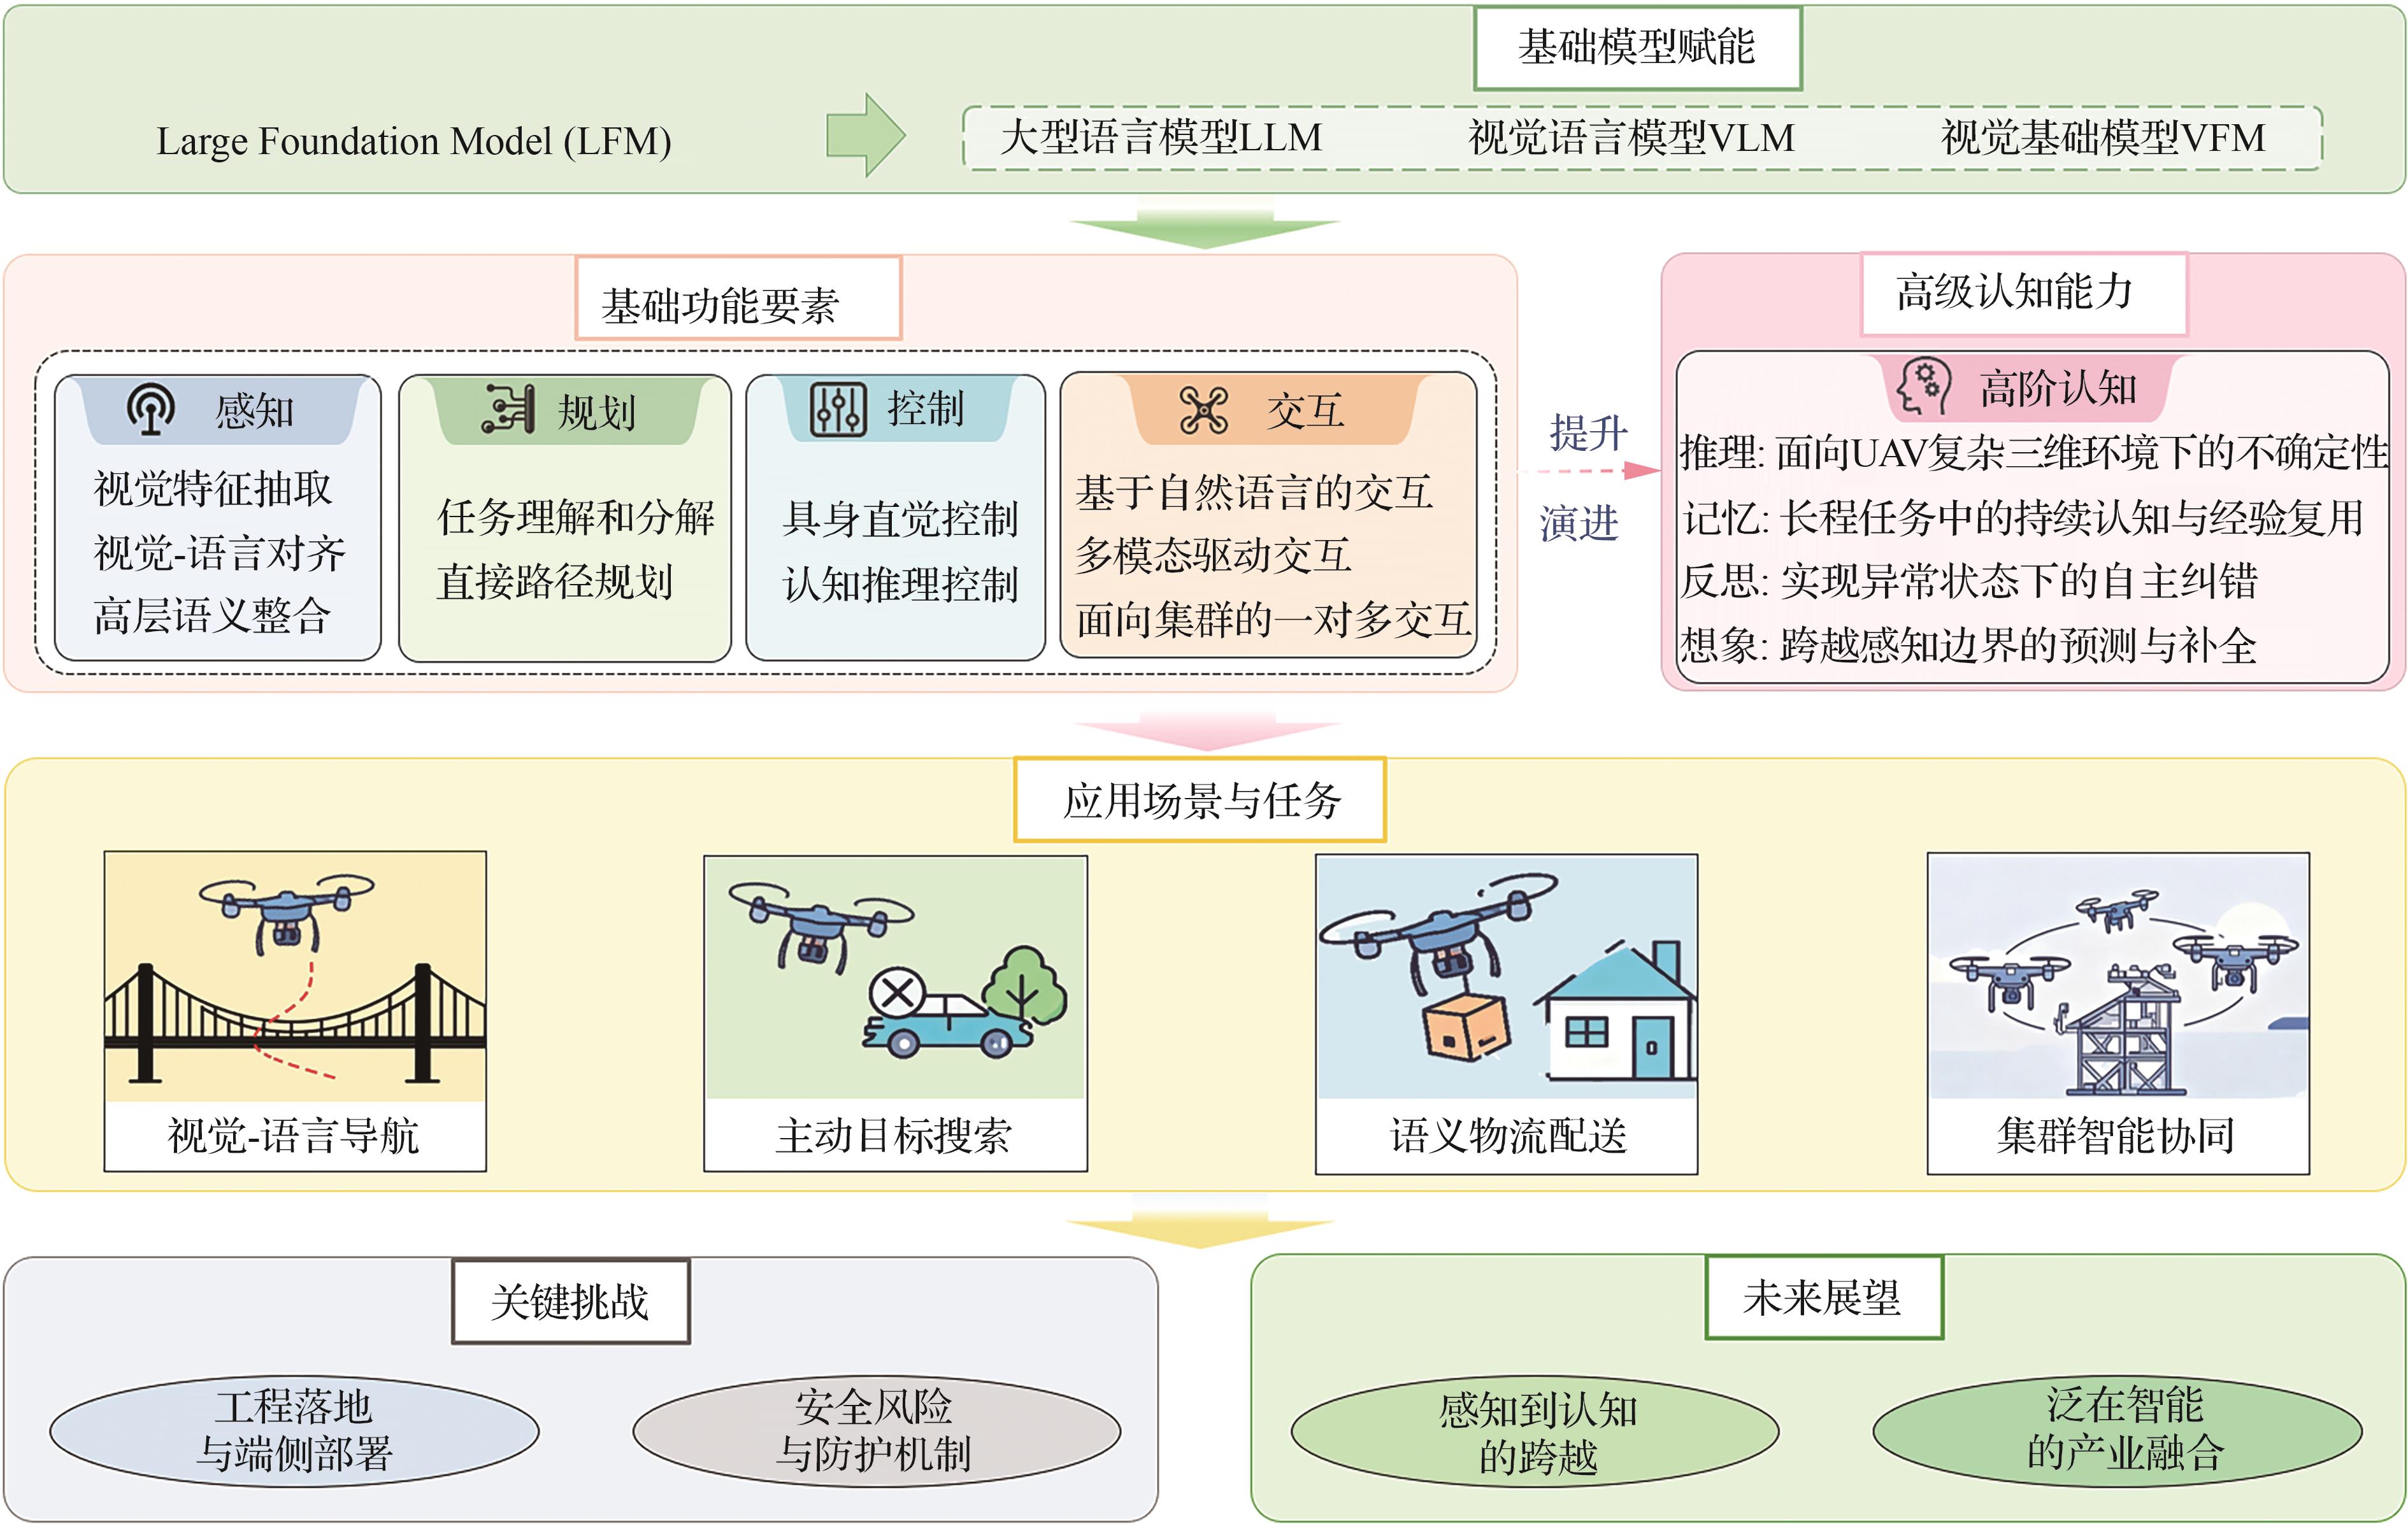
Fig.2
Intelligent upgrade of basic UAV functional modules (perception, planning, control, and interaction etc) empowered by various LFMs (including LLM, VLM, and VFM)
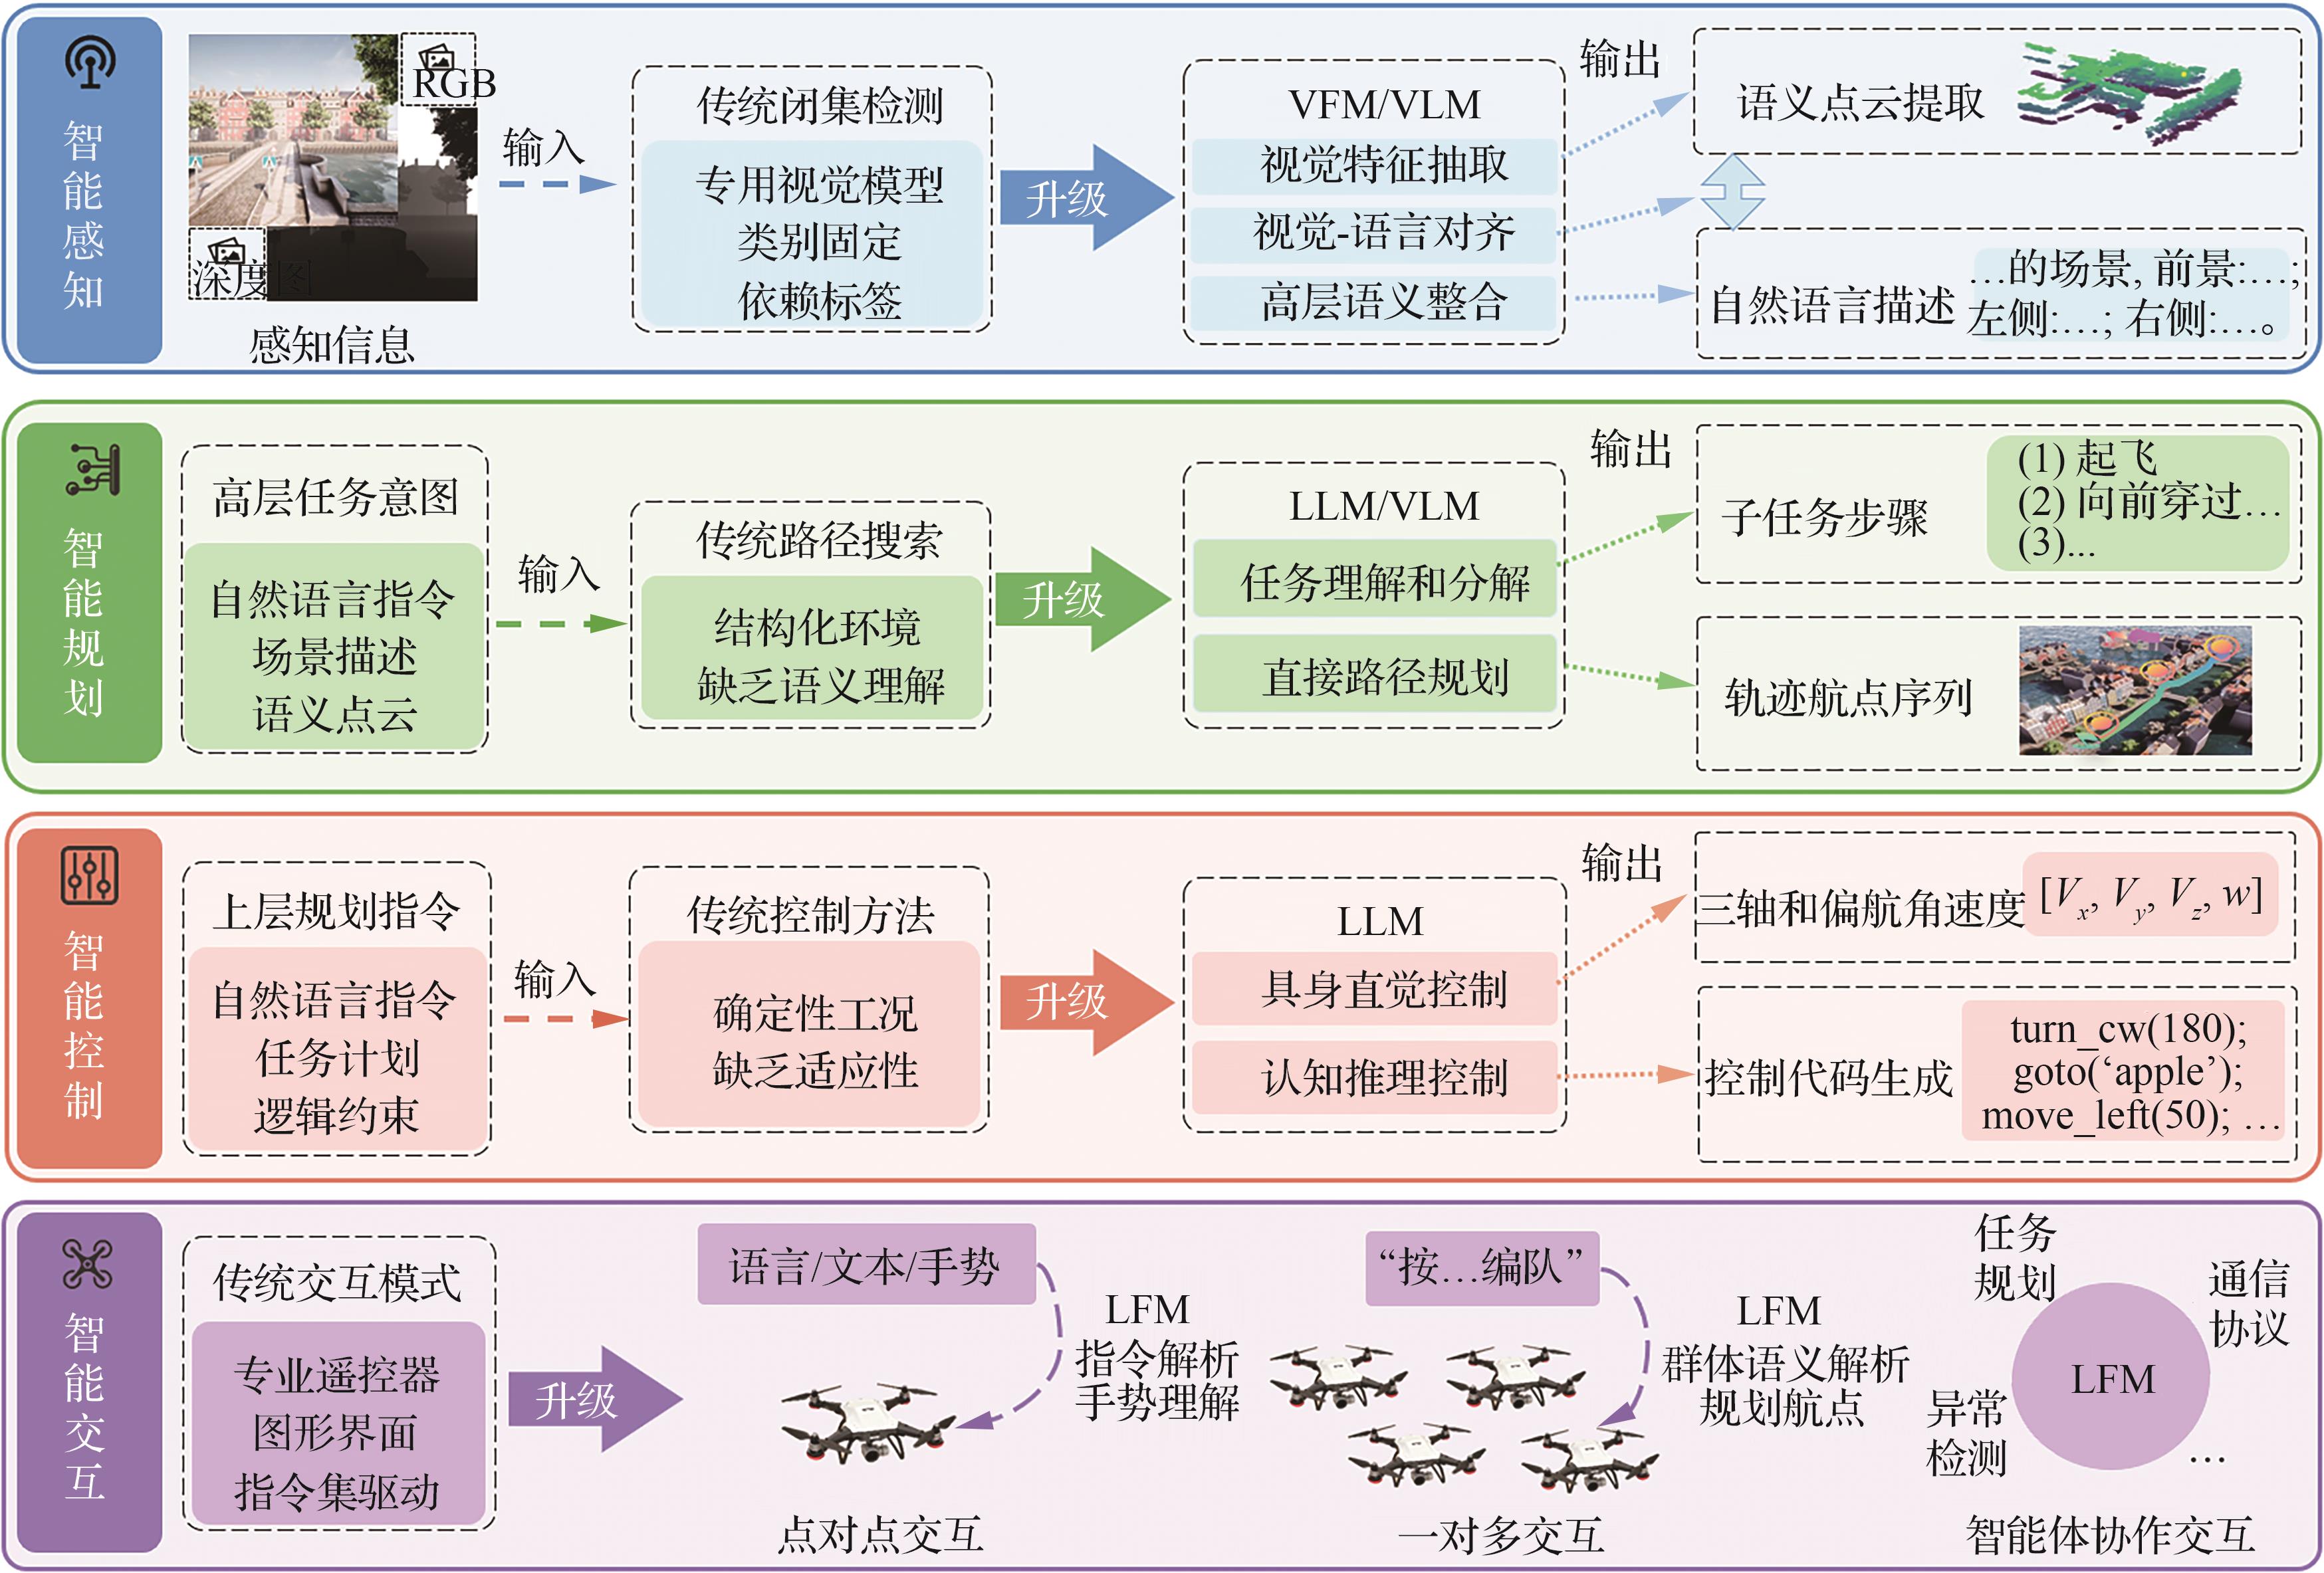
Fig.3
High-level cognitive capabilities empowered by LFM
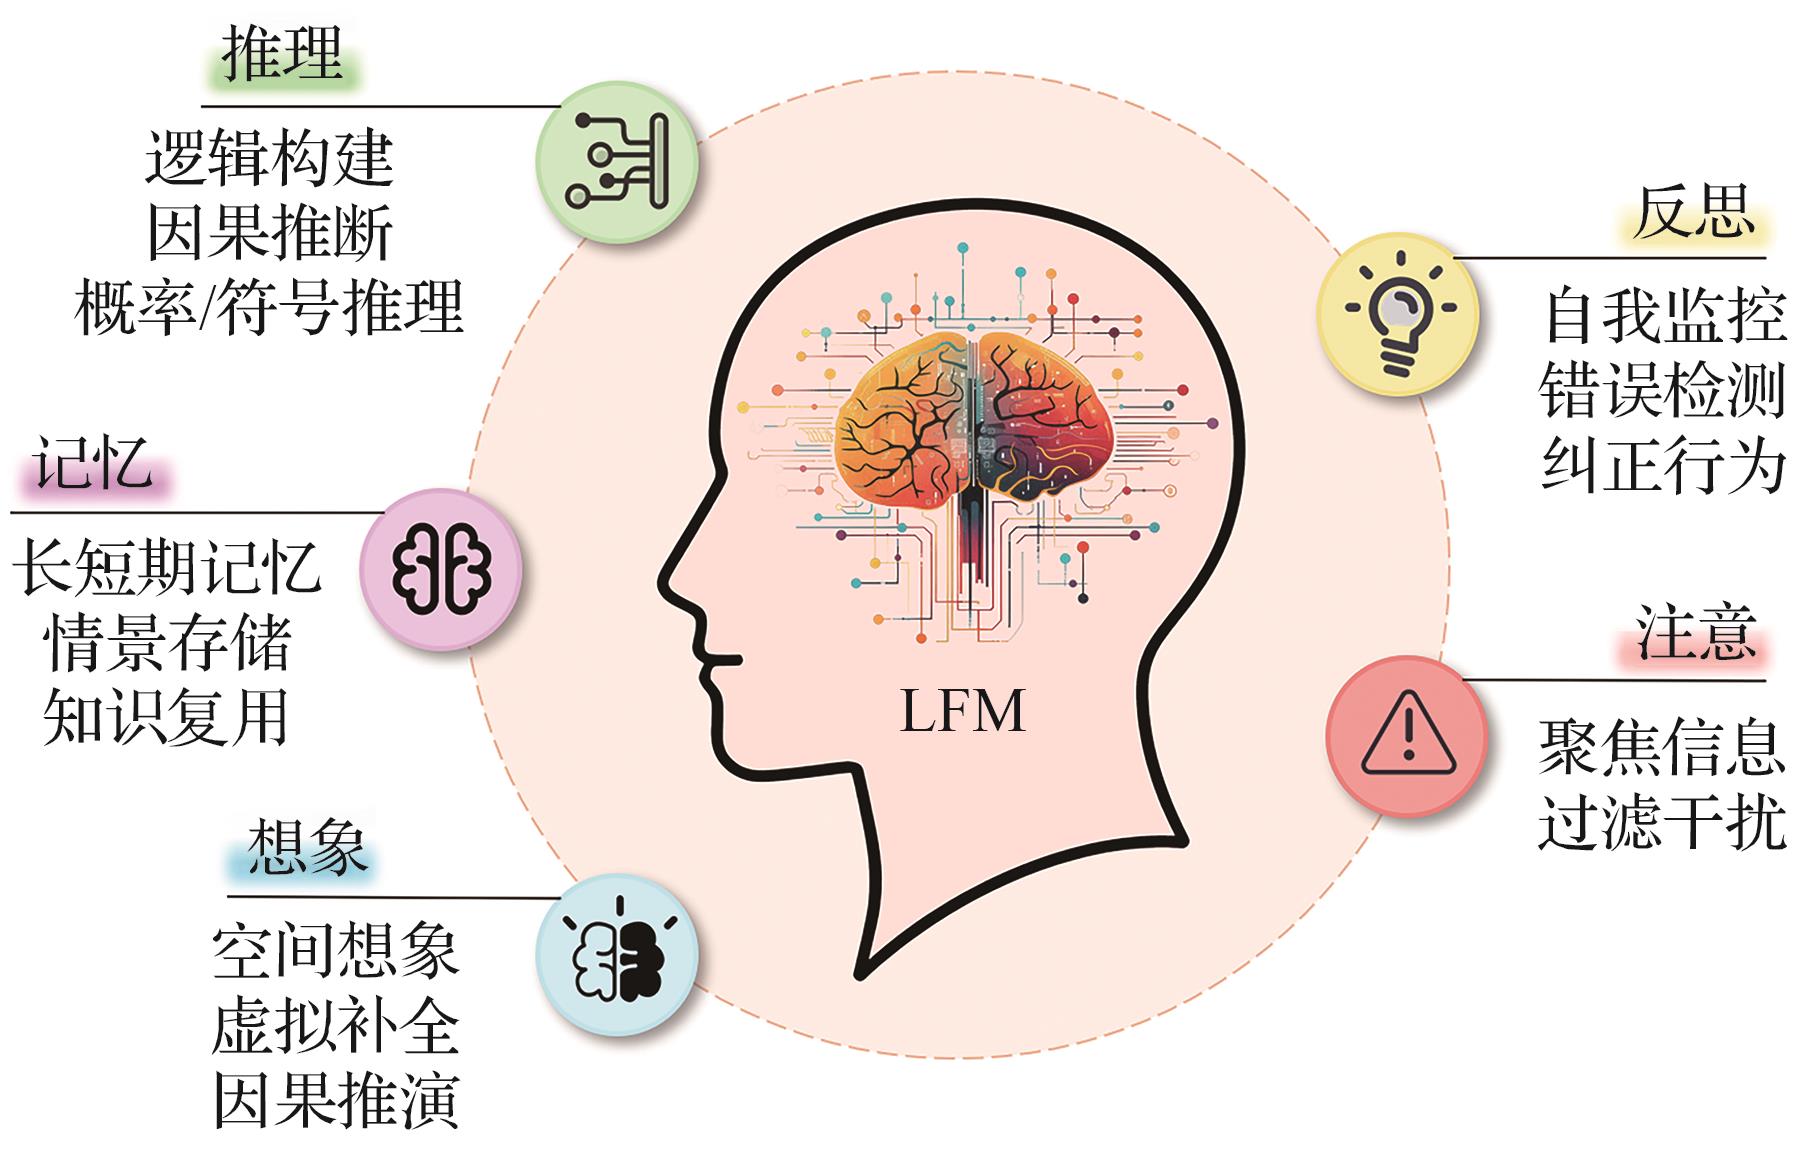
Fig.4
Four typical UAV decision-making tasks empowered by various LFMs
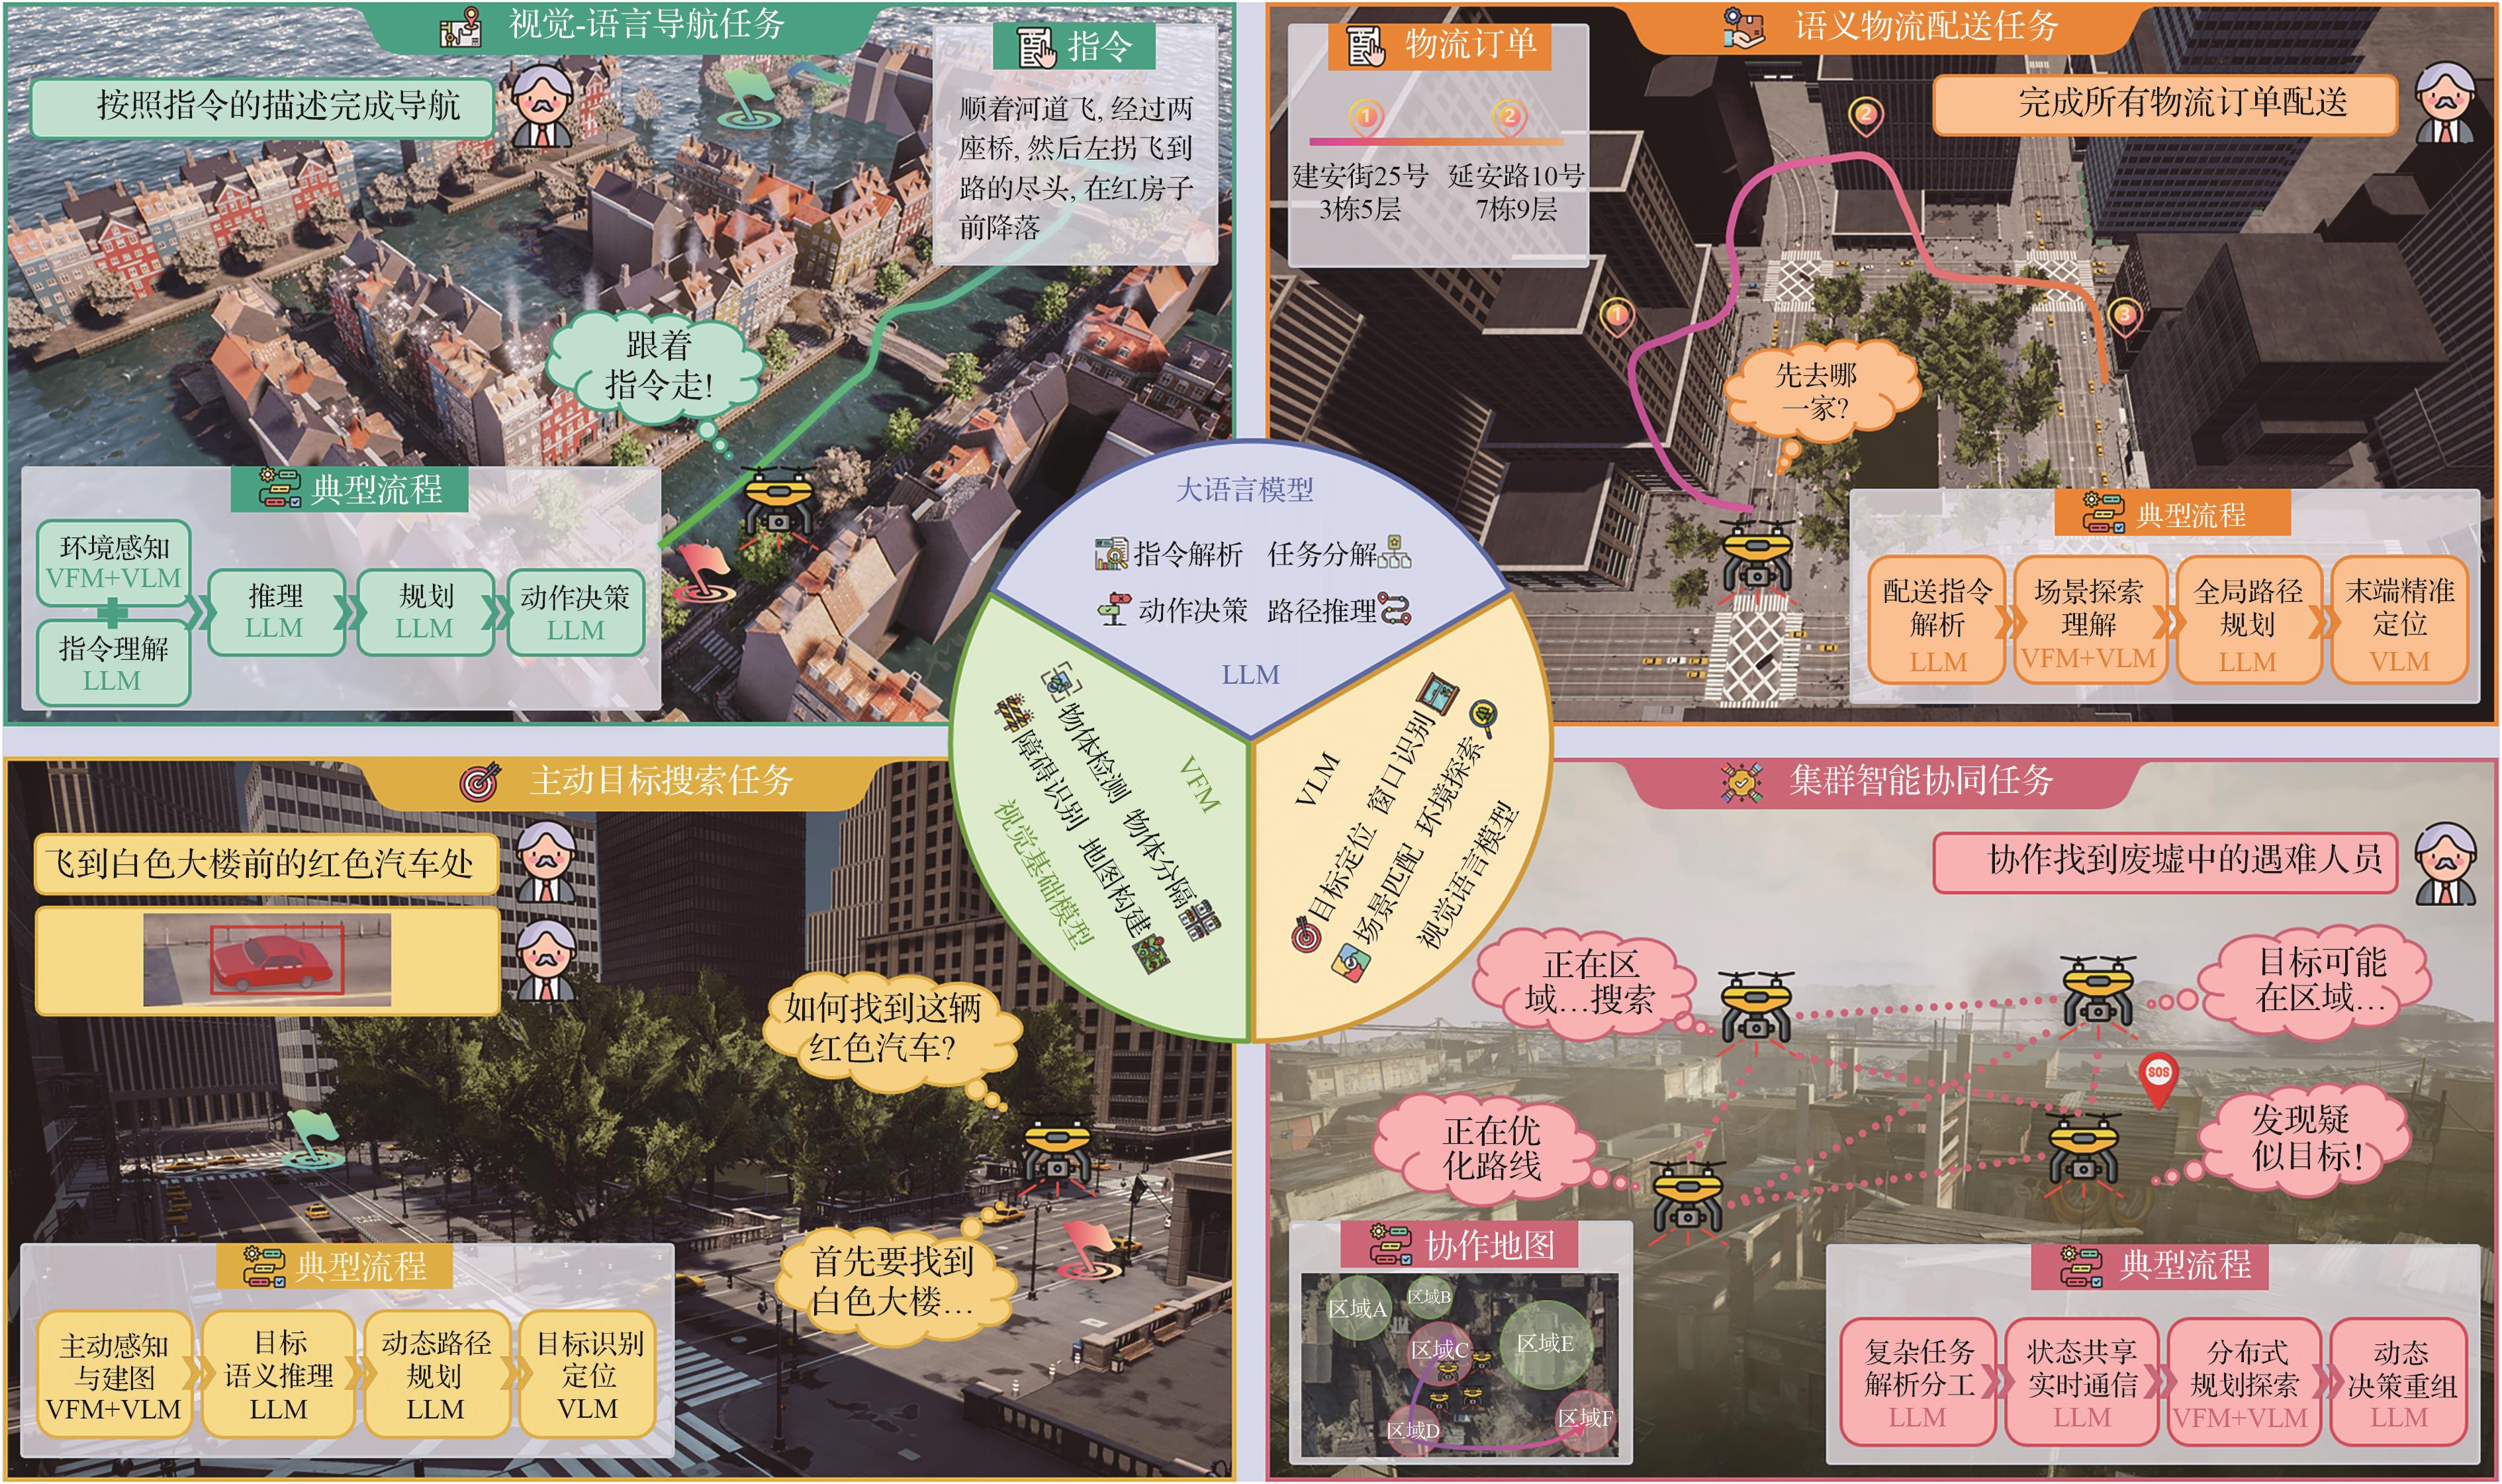
Table 1
A systematic review of four typical UAV decision-making tasks: Comparative analysis covering benchmarks, evaluation metrics, representative works, LFM paradigms, deployment and validation
| 任务类型 | 代表基准和指标 | 方法 | 相关LFM | LFM赋能范式 | 模型部署 平台 | 实验 类型 |
|---|---|---|---|---|---|---|
视觉-语言 导航 (4.1节) | 代表基准: AerialVLN、CityNav 常用指标: NE、SR、OSR、SPL、sDTW | STMR | GPT-4o (LLM) | 指令+环境表征到动作推理 | 云 (API) | 仿真+ 实机 |
Grounding DINO (VFM) | 开放词汇目标检测 | 机载平台 | ||||
Tokenize Anything (VFM) | 精细化语义分割 | |||||
| CityNavAgent | GPT-4V (VLM) | 生成场景物体描述; 多模态融合输出高层子目标 | 云 (API) | 仿真 | ||
Grounding DINO (VFM) | 开放词汇目标检测 | 本地服务器 | ||||
Segment Anything (VFM) | 精细化语义分割 | |||||
| GeoNav | GPT-3.5-turbo (LLM) | 指令解析提取目标属性 | 云 (API) | 仿真 | ||
| GPT-4o (VLM) | 构建分层场景图并导航 | |||||
Grounding DINO (VFM) | 开放词汇目标检测 | 本地服务器 | ||||
Segment Anything (VFM) | 精细化语义分割 | |||||
主动 目标搜索 (4.2节) | 代表基准: OpenUAV、CityAVOS 常用指标:NE、SR、MSS、OSR、SPL | PRPSearcher | GPT-4o (VLM) | 构建3D认知地图指导探索 | 云 (API) | 仿真 |
| Grounded-SAM (VFM) | 精细化语义分割 | 本地服务器 | ||||
| UAV-VLRR | GPT-4o (LLM) | 指令解析提取目标类别 | 云 (API) | 仿真+ 实机 | ||
| Molmo-7B (VLM) | 像素级目标与障碍定位 | 本地服务器 | ||||
语义 物流配送 (4.3节) | 代表基准: VLD 常用指标: SR、SPL、 Average Steps | LogisticsVLN | DeepSeek-R1-Distill-Qwen-14B (LLM) | CoT解析提取楼层与标志物 | 未提及 (适用边/端侧部署) | 仿真 |
| Qwen2-VL-7B (VLM) | 楼层估计/目标检测/探索 | |||||
集群 智能协同 (4.4节) | 代表基准: 模拟或现实环境 常用指标:NASA-TLX、编队形状识别准确率、用户问卷 | FlockGPT | GPT-4 (LLM) | 由自然语言解析编队参数 | 云 (API) | 仿真+ 实机 |
| LLM-CRF | LLaVA-1.6 (VLM) | 由视觉输入解析结构化语义 | 本地服务器 | 仿真 | ||
| Qwen-14B-Chat (LLM) | 多模态融合生成包含摘要、推理链和可执行代码的可执行任务包 |
Fig.5
Opportunities, challenges, and future prospects of UAV intelligent upgrades empowered by LFMs
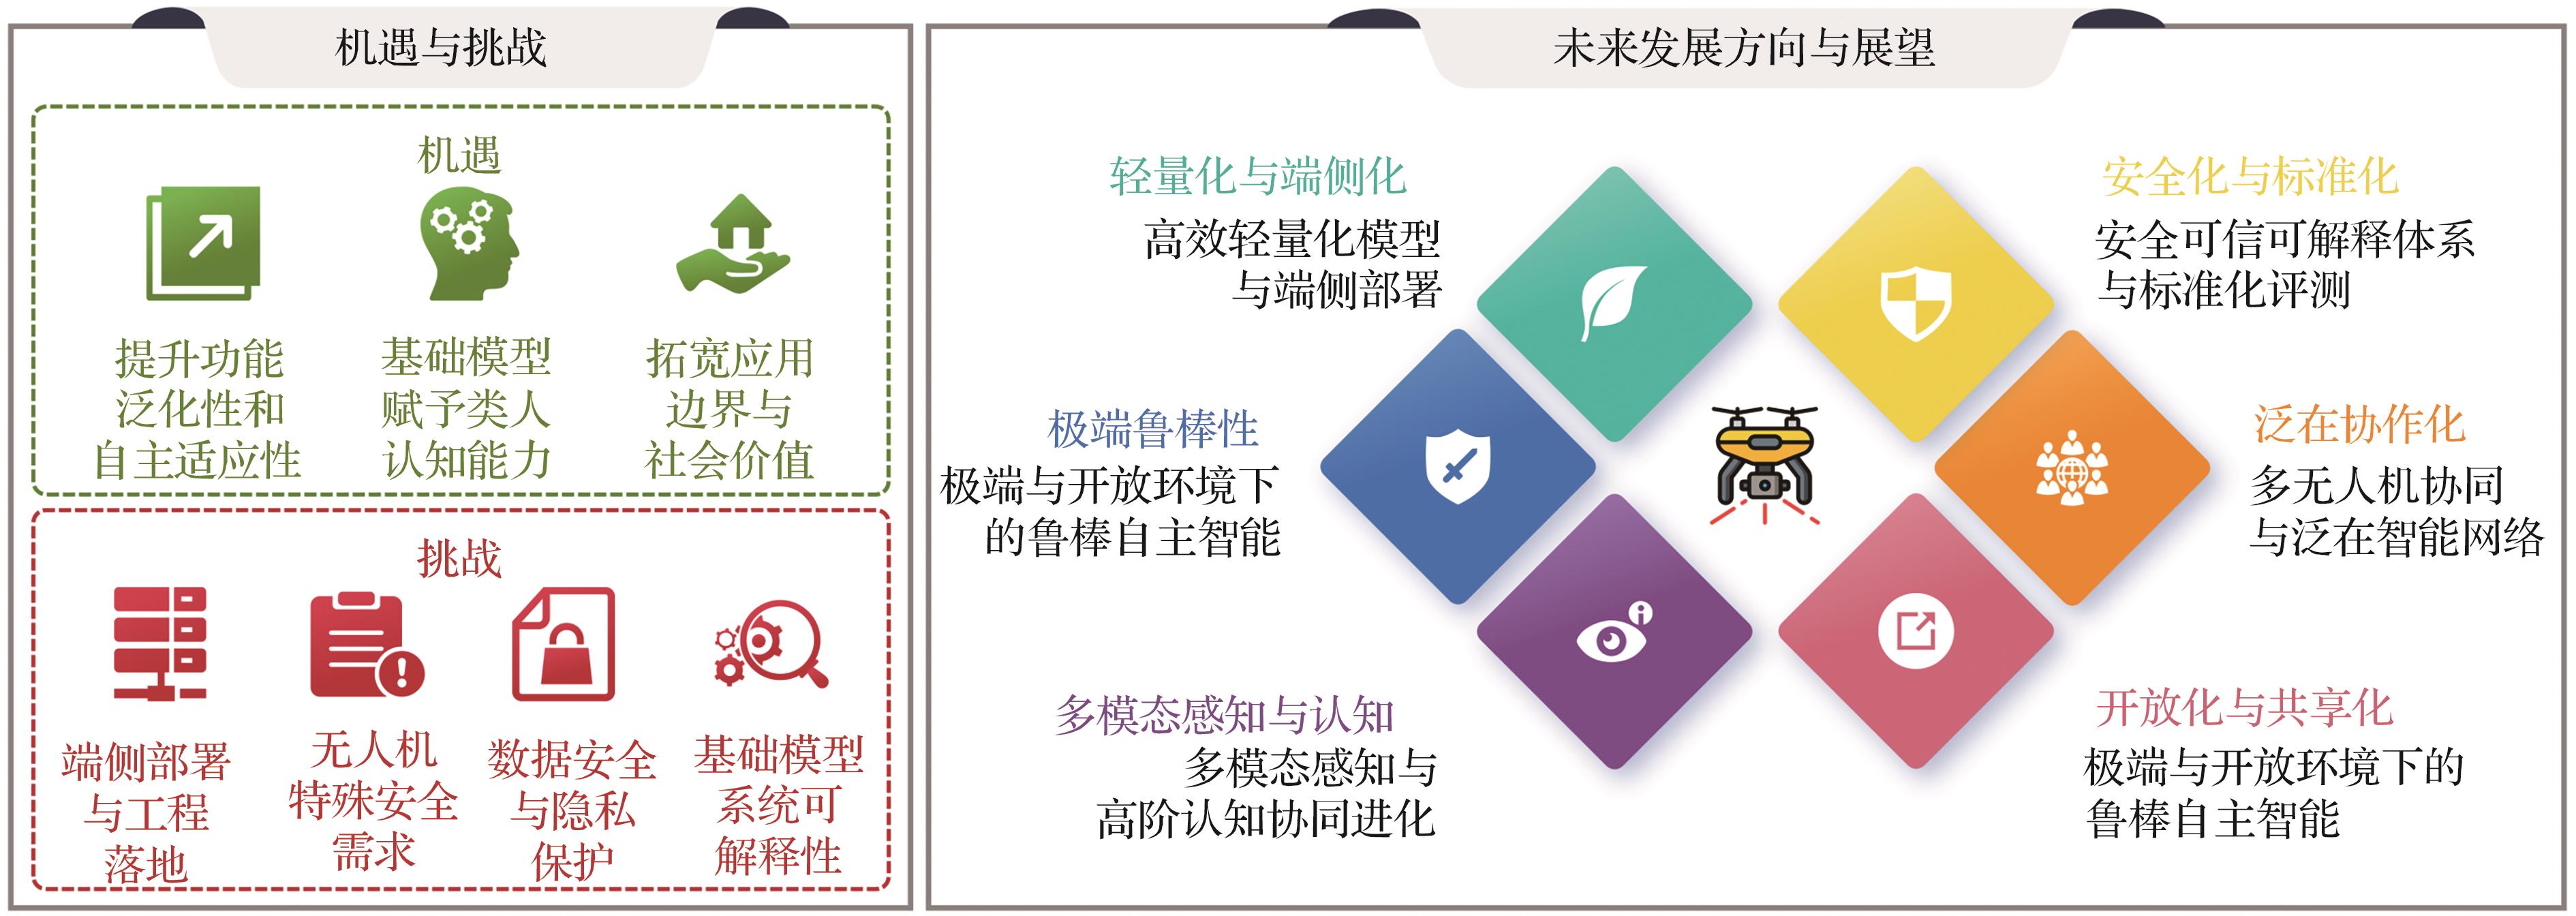
Table 2
Statistics of computing power and LLM adaptability of mainstream airborne computing platforms
| 平台厂商 | 芯片型号 | 算力/TOPS | 显存/GB | 功耗/W | 可用模型规模/B |
|---|---|---|---|---|---|
| 英伟达 | AGX Orin | 275 | 32/64 | 15~60 | ≤70 |
| Orin NX | 157 | 8/16 | 10~40 | ≤14 | |
| Orin Nano | 67 | 4/8 | 7~25 | ≤4 | |
| 华为昇腾 | Atlas 200I A2 | 20 | 4/8/12 | 25 | ≤7 |
| 瑞芯 | RK3588 | 6 | 8~16 | 2~10 | ≤10 |
| 酷芯 | AR9481 | 8 | 1 | ≤1 |
| [1] | BARNHART R K, MARSHALL D M, SHAPPEE E. Introduction to unmanned aircraft systems (3rd ed.)[M]. Boca Raton: CRC Press, 2021: 56-70. |
| [2] | ZHANG W, GAO C, YU S, et al. CityNavAgent: Aerial vision-and-language navigation with hierarchical semantic planning and global memory[DB/OL]. arXiv Preprint: 2505.05622; 2025. |
| [3] | RAVICHANDRAN Z, MURALI V, TZES M, et al. SPINE: Online semantic planning for missions with incomplete natural language specifications in unstructured environments[C]∥2025 IEEE International Conference on Robotics and Automation (ICRA). Piscataway: IEEE Press, 2025. |
| [4] | WANG X, YANG D, LIAO Y, et al. UAV-flow Colosseo: A real-world benchmark for flying-on-a-word UAV imitation learning[DB/OL]. arXiv Preprint: 2505.15725; 2025. |
| [5] | WANG Z, CHEN J, ZHENG X, et al. Hi AirStar, guide me to the badminton court[C]∥Proceedings of the 33rd ACM International Conference on Multimedia. New York: ACM, 2025. |
| [6] | LU P, PENG B, CHENG H, et al. Chameleon: Plug-and-play compositional reasoning with large language models[J]. Advances in Neural Information Processing Systems, 2023, 36: 43447-43478. |
| [7] | KE F, CAI Z, JAHANGARD S, et al. HYDRA: A hyper agent for dynamic compositional visual reasoning[C]∥LEONARDIS A, RICCI E, ROTH S, et al. Computer vision-ECCV 2024. Cham: Springer Nature Switzerland, 2025. |
| [8] | SHAH D J, RUSHTON P, SINGLA S, et al. Rethinking reflection in pre-training[DB/OL]. arXiv Preprint: 2504.04022; 2025. |
| [9] | YANG Z, YU X, CHEN D, et al. Machine mental imagery: Empower multimodal reasoning with latent visual tokens[DB/OL]. arXiv Preprint: 2506.17218; 2025. |
| [10] | DEVLIN J, CHANG M W, LEE K, et al. BERT: Pre-training of deep bidirectional transformers for language understanding[C]∥2019 Conference of the North American. Minneapolis: Association for Computational Linguistics, 2019. |
| [11] | RADFORD A, WU J, CHILD R, et al. Language models are unsupervised multitask learners[J]. OpenAI Blog, 2019, 1(8): 9. |
| [12] | YANG Z, DAI Z, YANG Y, et al. XLNet: Generalized autoregressive pretraining for language understanding[J]. Advances in Neural Information Processing Systems, 2019, 32. |
| [13] | RAFFEL C, SHAZEER N, ROBERTS A, et al. Exploring the limits of transfer learning with a unified text-to-text transformer[J]. Journal of Machine Learning Research, 2020, 21(140): 1-67. |
| [14] | OPENAI. Introducing GPT-5[EB/OL]. (2025-09-02)[2025-11-27]. . |
| [15] | Introducing OpenAI o 3 and o4 -mini[EB/OL]. (2025-04-16) [2025-11-27]. . |
| [16] | ANTHROPIC. Introducing Claude 4[EB/OL]. (2025-05-22)[2025-11-27]. . |
| [17] | GUO D, YANG D, ZHANG H, et al. Deepseek-r1: Incentivizing reasoning capability in LLMs via reinforcement learning[DB/OL]. arXiv Preprint: 2501.12948; 2025. |
| [18] | YANG A, LI A, YANG B, et al. Qwen3 technical report[DB/OL]. arXiv Preprint: 2505.09388; 2025. |
| [19] | BROWN T, MANN B, RYDER N, et al. Language models are few-shot learners[J]. Advances in Neural Information Processing Systems, 2020, 33: 1877-1901. |
| [20] | WEI J, WANG X, SCHUURMANS D, et al. Chain-of-thought prompting elicits reasoning in large language models[J]. Advances in Neural Information Processing Systems, 2022, 35: 24824-24837. |
| [21] | SHAZEER N, MIRHOSEINI A, MAZIARZ K, et al. Outrageously large neural networks: The sparsely-gated mixture-of-experts layer[DB/OL]. arXiv Preprint: 1701.06538; 2017. |
| [22] | TAN H, BANSAL M. LXMERT: Learning cross-modality encoder representations from transformers[DB/OL]. arXiv Preprint: 1908.07490; 2019. |
| [23] | LI X, YIN X, LI C, et al. Oscar: Object-semantics aligned pre-training for vision-language tasks[C]∥Computer Vision-ECCV 2020. Cham: Springer International Publishing, 2020. |
| [24] | CHEN Y C, LI L, YU L, et al. UNITER: UNiversal image-TExt representation learning[C]∥Computer Vision-ECCV 2020. Cham: Springer Cham, 2020. |
| [25] | SUN C, MYERS A, VONDRICK C, et al. VideoBERT: A joint model for video and language representation learning[C]∥Proceedings of the IEEE/CVF international conference on computer vision. Piscataway: IEEE Press, 2019. |
| [26] | LI L H, YATSKAR M, YIN D, et al. VisualBERT: A simple and performant baseline for vision and language[DB/OL]. arXiv Preprint: 1908.03557; 2019. |
| [27] | LIU H T, LI C Y, WU Q Y, et al. Visual instruction tuning[J]. Advances in Neural Information Processing Systems, 2023, 36: 34892-34916. |
| [28] | ALAYRAC J B, DONAHUE J, LUC P, et al. Flamingo: A visual language model for few-shot learning[J]. Advances in Neural Information Processing Systems, 2022, 35: 23716-23736. |
| [29] | LI J, LI D, XIONG C, et al. BLIP: Bootstrapping language-image pre-training for unified vision-language understanding and generation[C]∥International conference on machine learning. New York: PMLR, 2022. |
| [30] | RADFORD A, KIM J W, HALLACY C, et al. Learning transferable visual models from natural language supervision[C]∥International conference on machine learning. New York: PMLR, 2021. |
| [31] | DOSOVITSKIY A. An image is worth 16×16 words: Transformers for image recognition at scale[DB/OL]. arXiv Preprint: 2010.11929; 2020. |
| [32] | OPENAI. GPT-4V(ision) system card[EB/OL]. (2025-08-25) [2025-11-27]. . |
| [33] | HURST A, LERER A, GOUCHER A P, et al. Gpt-4o system card[DB/OL]. arXiv Preprint: 2410.21276; 2024. |
| [34] | ANTHROPIC. Introducing the next generation of Claude[EB/OL]. (2025-08-27)[2025-11-27]. . |
| [35] | COMANICI G, BIEBER E, SCHAEKERMANN M, et al. Gemini 2.5: Pushing the frontier with advanced reasoning, multimodality, long context, and next generation agentic capabilities[DB/OL]. arXiv Preprint: 2507.06261; 2025. |
| [36] | BAI J, BAI S, YANG S, et al. Qwen-VL: A versatile vision-language model for understanding, localization, text reading, and beyond[DB/OL]. arXiv Preprint: 2308.12966; 2023. |
| [37] | CHEN Z, WU J, WANG W, et al. InternVL: Scaling up vision foundation models and aligning for generic visual-linguistic tasks[C]∥Proceedings of the IEEE/CVF conference on computer vision and pattern recognition. Piscataway: IEEE Press, 2024. |
| [38] | WANG W, LV Q, YU W, et al. CogVLM: Visual expert for pretrained language models[J]. Advances in Neural Information Processing Systems, 2024, 37: 121475-121499. |
| [39] | CARON M, TOUVRON H, MISRA I, et al. Emerging properties in self-supervised vision transformers[C]∥Proceedings of the IEEE/CVF international conference on computer vision. Piscataway: IEEE Press, 2021. |
| [40] | CARON M, TOUVRON H, MISRA I, et al. Emerging properties in self-supervised vision transformers[C]∥Proceedings of the IEEE/CVF international conference on computer vision. Piscataway: IEEE Press, 2021. |
| [41] | OQUAB M, DARCET T, MOUTAKANNI T, et al. Dinov2: Learning robust visual features without supervision[DB/OL]. arXiv Preprint: 2304.07193; 2023. |
| [42] | KIRILLOV A, MINTUN E, RAVI N, et al. Segment anything[C]∥Proceedings of the IEEE/CVF international conference on computer vision. Piscataway: IEEE Press, 2023. |
| [43] | LI L H, ZHANG P, ZHANG H, et al. Grounded language-image pre-training[C]∥Proceedings of the IEEE/CVF conference on computer vision and pattern recognition. Piscataway: IEEE Press, 2022. |
| [44] | CHENG T, SONG L, GE Y, et al. Yolo-world: Real-time open-vocabulary object detection[C]∥Proceedings of the IEEE/CVF conference on computer vision and pattern recognition. Piscataway: IEEE Press, 2024. |
| [45] | LIU S, ZENG Z, REN T, et al. Grounding DINO: Marrying DINO with grounded pre-training for open-set object detection[C]∥Computer Vision-ECCV 2024. Cham: Springer Cham, 2025. |
| [46] | LÜDDECKE T, ECKER A. Image segmentation using text and image prompts[C]∥Proceedings of the IEEE/CVF conference on computer vision and pattern recognition. Piscataway: IEEE Press, 2022. |
| [47] | YUAN H, LI X, ZHOU C, et al. Open-vocabulary SAM: Segment and recognize twenty-thousand classes interactively[C]∥Computer Vision-ECCV 2024. Cham: Springer Cham, 2025. |
| [48] | WANG X, ZHANG X, CAO Y, et al. SegGPT: towards segmenting everything in context[C]∥Proceedings of the IEEE/CVF International Conference on Computer Vision. Piscataway: IEEE Press, 2023. |
| [49] | ZOU X, YANG J, ZHANG H, et al. Segment everything everywhere all at once[J]. Advances in Neural Information Processing Systems, 2023, 36: 19769-19782. |
| [50] | BHAT S F, BIRKL R, WOFK D, et al. ZoeDepth: Zero-shot transfer by combining relative and metric depth[DB/OL]. arXiv Preprint: 2302.12288; 2023. |
| [51] | YANG L, KANG B, HUANG Z, et al. Depth anything: Unleashing the power of large-scale unlabeled data[C]∥Proceedings of the IEEE/CVF conference on computer vision and pattern recognition. Piscataway: IEEE Press, 2024. |
| [52] | BOCHKOVSKII A, DELAUNOY A, GERMAIN H, et al. Depth pro: Sharp monocular metric depth in less than a second[DB/OL]. arXiv Preprint: 2410.02073; 2024. |
| [53] | ZITKOVICH B, YU T, XU S, et al. Rt-2: Vision-language-action models transfer web knowledge to robotic control[C]∥Conference on Robot Learning. New York: PMLR, 2023. |
| [54] | KIM M J, PERTSCH K, KARAMCHETI S, et al. Openvla: An open-source vision-language-action model[DB/OL]. arXiv Preprint: 2406.09246; 2024. |
| [55] | WEN J, ZHU Y, LI J, et al. TinyVLA: Toward fast, data-efficient vision-language-action models for robotic manipulation[J]. IEEE Robotics and Automation Letters, 2025, 10(4): 3988-3995. |
| [56] | MEI A, ZHU G N, ZHANG H, et al. ReplanVLM: Replanning robotic tasks with visual language models[J]. IEEE Robotics and Automation Letters, 2024, 9(11): 10201-10208. |
| [57] | SKRETA M, ZHOU Z, YUAN J L, et al. Replan: Robotic replanning with perception and language models[DB/OL]. arXiv Preprint: 2401.04157; 2024. |
| [58] | AO S, SALIM F D, KHAN S. EMAC+: Embodied multimodal agent for collaborative planning with VLM+ LLM[DB/OL]. arXiv Preprint: 2505.19905; 2025. |
| [59] | ZHAO Q, LU Y, KIM M J, et al. Cot-vla: Visual chain-of-thought reasoning for vision-language-action models[C]∥Proceedings of the Computer Vision and Pattern Recognition Conference. Piscataway: IEEE Press, 2025. |
| [60] | SUN Q, HONG P, PALA T D, et al. Emma-X: An embodied multimodal action model with grounded chain of thought and look-ahead spatial reasoning[C]∥63rd Annual Meeting of the Association for Computational Linguistics Vienna: Association for Computational Linguistics, 2025. |
| [61] | LIN F, NAI R, HU Y, et al. OneTwoVLA: A unified vision-language-action model with adaptive reasoning[DB/OL]. arXiv Preprint: 2505.11917; 2025. |
| [62] | SERPIVA V, LYKOV A, MYSHLYAEV A, et al. RaceVLA: VLA-based racing drone navigation with human-like behaviour[DB/OL]. arXiv Preprint: 2503.02572; 2025. |
| [63] | HE K, ZHANG X, REN S, et al. Deep residual learning for image recognition[C]∥Proceedings of the IEEE conference on computer vision and pattern recognition. Piscataway: IEEE Press, 2016. |
| [64] | HUSSAIN M. YOLO-v1 to YOLO-v8, the rise of YOLO and its complementary nature toward digital manufacturing and industrial defect detection[J]. Machines, 2023, 11(7): 677. |
| [65] | REN S, HE K, GIRSHICK R, et al. Faster R-CNN: Towards real-time object detection with region proposal networks[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2016, 39(6): 1137-1149. |
| [66] | ZHANG X, TIAN Y, LIN F, et al. LogisticsVLN: Vision-language navigation for low-altitude terminal delivery based on agentic UAVs[DB/OL]. arXiv Preprint: 2505.03460; 2025. |
| [67] | HART P E, NILSSON N J, RAPHAEL B. A formal basis for the heuristic determination of minimum cost paths[J]. IEEE transactions on Systems Science and Cybernetics, 1968, 4(2): 100-107. |
| [68] | LAVALLE S. Rapidly-exploring random trees: A new tool for path planning[R]. Research Report 9811, 1998. |
| [69] | SHAH D, OSIŃSKI B, LEVINE S, et al. Lm-nav: Robotic navigation with large pre-trained models of language, vision, and action[C]∥Conference on robot learning. New York: PMLR, 2023. |
| [70] | AHN M, BROHAN A, BROWN N, et al. Do as I can, not as I say: Grounding language in robotic affordances[DB/OL]. arXiv Preprint: 2204.01691; 2022. |
| [71] | XIAO J, TSAO C W, ZHANG Y, et al. FM-planner: Foundation model guided path planning for autonomous drone navigation[DB/OL]. arXiv Preprint: 2505.20783; 2025. |
| [72] | BAI J, BAI S, CHU Y, et al. Qwen technical report[DB/OL]. arXiv Preprint: 2309.16609; 2023. |
| [73] | TEAM G, MESNARD T, HARDIN C, et al. Gemma: Open models based on Gemini research and technology[DB/OL]. arXiv Preprint: 2403.08295; 2024. |
| [74] | DUBEY A, JAUHRI A, PANDEY A, et al. The llama 3 herd of models[DB/OL]. arXiv Preprint: 2407.21783; 2024. |
| [75] | WATKINS C J, DAYAN P. Q-learning[J]. Machine learning, 1992, 8(3-4): 279-292. |
| [76] | CHEN G, YU X, LING N, et al. TypeFly: Flying drones with large language model[DB/OL]. arXiv Preprint: 2312.14950; 2023. |
| [77] | TAGLIABUE A, KONDO K, ZHAO T, et al. REAL: Resilience and adaptation using large language models on autonomous aerial robots[C]∥2024 IEEE 63rd Conference on Decision and Control (CDC). Piscataway: IEEE Press, 2024. |
| [78] | WANG W, LI Y, JIAO L, et al. GSCE: A prompt framework with enhanced reasoning for reliable LLM-driven drone control[C]∥2025 International Conference on Unmanned Aircraft Systems (ICUAS). Piscataway: IEEE Press, 2025. |
| [79] | YOO M, NA Y, SONG H, et al. Motion estimation and hand gesture recognition-based human-UAV interaction approach in real time[J]. Sensors, 2022, 22(7): 2513. |
| [80] | 万开方, 吴志林, 武韫晖, 等. 拒止环境下基于深度强化学习的多无人机协同定位[J]. 航空学报, 2025, 46(8): 331024. |
| WAN K F, WU Z L, WU Y H, et al. Multi-UAV cooperative localization based on deep reinforcement learning in denied environments[J]. Acta Aeronautica et Astronautica Sinica, 2025, 46(8): 331024 (in Chinese). | |
| [81] | CLADERA F, RAVICHANDRAN Z, HUGHES J, et al. Air-ground collaboration for language-specified missions in unknown environments[DB/OL]. arXiv Preprint: 2505.09108; 2025. |
| [82] | RAVICHANDRAN Z, CLADERA F, HUGHES J, et al. Deploying foundation model-enabled air and ground robots in the field: Challenges and opportunities[DB/OL]. arXiv Preprint: 2505.09477; 2025. |
| [83] | LYKOV A, KARAF S, MARTYNOV M, et al. FlockGPT: Guiding UAV flocking with linguistic orchestration[C]∥2024 IEEE International Symposium on Mixed and Augmented Reality Adjunct (ISMAR-Adjunct). Piscataway: IEEE Press, 2024. |
| [84] | DHARMALINGAM B, MUKHERJEE R, PIGGOTT B, et al. Aero-LLM: A distributed framework for secure UAV communication and intelligent decision-making[DB/OL]. arXiv Preprint: 2502.05220; 2025. |
| [85] | DAI S, MA Z, LUO Z, et al. MM-UAVBench: How well do multimodal large language models see, think, and plan in low-altitude UAV scenarios?[DB/OL]. arXiv Preprint: 2512.23219; 2025. |
| [86] | ZHU Z, XUE Y, CHEN X, et al. Large language models can learn rules[DB/OL]. arXiv Preprint: 2310.07064; 2023. |
| [87] | HAO S B, GU Y, MA H D, et al. Reasoning with language model is planning with world model[DB/OL]. arXiv Preprint: 2305.14992; 2023. |
| [88] | MOWER C E, WAN Y, YU H, et al. ROS-LLM: A ros framework for embodied ai with task feedback and structured reasoning[DB/OL]. arXiv Preprint: 2406.19741; 2024. |
| [89] | ZHANG W, WANG M, LIU G, et al. Embodied-reasoner: Synergizing visual search, reasoning, and action for embodied interactive tasks[DB/OL]. arXiv Preprint: 2503.21696; 2025. |
| [90] | CAI Z, CARDENAS C R, LEO K, et al. NEUSIS: A compositional neuro-symbolic framework for autonomous perception, reasoning, and planning in complex UAV search missions[J]. IEEE Robotics and Automation Letters, 2025, 10(9): 9502-9509. |
| [91] | GAO Y, WANG Z, JING L, et al. Aerial vision-and-language navigation via semantic-topo-metric representation guided LLM reasoning[DB/OL]. arXiv Preprint: 2410.08500; 2024. |
| [92] | ZHAO J, LIN X. General-purpose aerial intelligent agents empowered by large language models[DB/OL]. arXiv Preprint: 2503.08302; 2025. |
| [93] | ZHAO B, WANG Z, FANG J, et al. Embodied-R: Collaborative framework for activating embodied spatial reasoning in foundation models via reinforcement learning[C]∥Proceedings of the 33rd ACM International Conference on Multimedia. New York: ACM, 2025. |
| [94] | WANG G, XIE Y, JIANG Y, et al. Voyager: An open-ended embodied agent with large language models[DB/OL]. arXiv Preprint: 2305.16291; 2023. |
| [95] | WANG Z, LI X, YANG J, et al. Gridmm: Grid memory map for vision-and-language navigation[C]∥Proceedings of the IEEE/CVF International conference on computer vision. Piscataway: IEEE Press, 2023. |
| [96] | LI H, WANG Z, YANG X, et al. Memonav: Working memory model for visual navigation[C]∥Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2024. |
| [97] | ZHENG Q, LIU D, WANG C, et al. Esceme: Vision-and-language navigation with episodic scene memory[J]. International Journal of Computer Vision, 2025, 133(1): 254-274. |
| [98] | ZENG Q, YANG Q, DONG S, et al. Perceive, reflect, and plan: Designing LLM agent for goal-directed city navigation without instructions[DB/OL]. arXiv Preprint: 2408.04168; 2024. |
| [99] | LINGO R, ARROYO M, CHHAJER R. Enhancing LLM problem solving with reap: Reflection, explicit problem deconstruction, and advanced prompting[DB/OL]. arXiv Preprint: 2409.09415; 2024. |
| [100] | YANG Z, LIU J, CHEN P, et al. RILA: Reflective and imaginative language agent for zero-shot semantic audio-visual navigation[C]∥Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2024. |
| [101] | YU Z, LONG Y, YANG Z, et al. CorrectNav: Self-correction Flywheel empowers vision-language-action navigation model[DB/OL]. arXiv Preprint: 2508.10416; 2025. |
| [102] | HUANG Y, WU M, LI R, et al. VISTA: Generative visual imagination for vision-and-language navigation[DB/OL]. arXiv Preprint: 2505.07868; 2025. |
| [103] | PERINCHERRY A, KRANTZ J, LEE S. Do visual imaginations improve vision-and-language navigation agents?[C]∥Proceedings of the Computer Vision and Pattern Recognition Conference. Piscataway: IEEE Press, 2025. |
| [104] | ANDERSON P, WU Q, TENEY D, et al. Vision-and-language navigation: Interpreting visually-grounded navigation instructions in real environments[C]∥Proceedings of the IEEE conference on computer vision and pattern recognition. Piscataway: IEEE Press, 2018. |
| [105] | KU A, ANDERSON P, PATEL R, et al. Room-across-room: Multilingual vision-and-language navigation with dense spatiotemporal grounding[DB/OL]. arXiv Preprint: 2010.07954; 2020. |
| [106] | CHEN H, SUHR A, MISRA D, et al. Touchdown: Natural language navigation and spatial reasoning in visual street environments[C]∥Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2019. |
| [107] | LEE J, MIYANISHI T, KURITA S, et al. CityNav: Language-goal aerial navigation dataset with geographic information[DB/OL]. arXiv Preprint: 2406.14240; 2024. |
| [108] | DORBALA V S, SIGURDSSON G, PIRAMUTHU R, et al. CLIP-Nav: Using clip for zero-shot vision-and-language navigation[DB/OL]. arXiv Preprint: 2211.16649; 2022. |
| [109] | DORBALA V S, MULLEN JR J F, MANOCHA D. Can an embodied agent find your “cat-shaped mug”? LLM-based zero-shot object navigation[DB/OL]. arXiv Preprint: 2303.03480; 2023. |
| [110] | ZHOU G, HONG Y, WU Q. NavGPT: Explicit reasoning in vision-and-language navigation with large language models[J]. Proceedings of the AAAI Conference on Artificial Intelligence, 2024, 38(7): 7641-7649. |
| [111] | LONG Y, LI X, CAI W, et al. Discuss before moving: Visual language navigation via multi-expert discussions[C]∥2024 IEEE International Conference on Robotics and Automation (ICRA). Piscataway: IEEE Press, 2024. |
| [112] | LONG Y, CAI W, WANG H, et al. InstructNav: Zero-shot system for generic instruction navigation in unexplored environment[DB/OL]. arXiv Preprint: 2406.04882; 2024. |
| [113] | ZHOU G, HONG Y, WANG Z, et al. NavGPT-2: Unleashing navigational reasoning capability for large vision-language models[C]∥Computer Vision-ECCV 2024. Cham: Springer Cham, 2025. |
| [114] | SU Y, AN D, CHEN K, et al. Learning fine-grained alignment for aerial vision-dialog navigation[J]. Proceedings of the AAAI Conference on Artificial Intelligence, 2025, 39(7): 7060-7068. |
| [115] | XU H, HU Y, GAO C, et al. GeoNav: Empowering MLLMs with explicit geospatial reasoning abilities for language-goal aerial navigation[DB/OL]. arXiv Preprint: 2504.09587; 2025. |
| [116] | ZHAO G, LI G, PAN J, et al. Aerial vision-and-language navigation with grid-based view selection and map construction[DB/OL]. arXiv Preprint: 2503.11091; 2025. |
| [117] | LIN H, YANG X, WEN G, et al. Fast UAV object-searching in large-scale and complex environments[J]. IEEE Transactions on Cybernetics, 2025, 55(6): 2993-3004. |
| [118] | CHANGOLUISA CAIZA I D, MILAS A, MONTES GROVA M A, et al. Autonomous exploration of unknown 3D environments using a frontier-based collector strategy[C]∥2024 IEEE International Conference on Robotics and Automation (ICRA). Piscataway: IEEE Press, 2024. |
| [119] | PAPAIOANNOU S, KOLIOS P, THEOCHARIDES T, et al. 3D trajectory planning for UAV-based search missions: An integrated assessment and search planning approach[C]∥2021 International Conference on Unmanned Aircraft Systems (ICUAS). Piscataway: IEEE Press, 2021. |
| [120] | BARTOLOMEI L, TEIXEIRA L, CHLI M. Fast multi-UAV decentralized exploration of forests[J]. IEEE Robotics and Automation Letters, 2023, 8(9): 5576-5583. |
| [121] | SANDINO J, CACCETTA P A, SANDERSON C, et al. Reducing object detection uncertainty from RGB and thermal data for UAV outdoor surveillance[C]∥2022 IEEE Aerospace Conference (AERO). Piscataway: IEEE Press, 2022. |
| [122] | GUPTA A, BESSONOV D, LI P. A decision-theoretic approach to detection-based target search with a UAV[C]∥2017 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS). Piscataway: IEEE Press, 2017. |
| [123] | XU K, ZHENG L, WEI M, et al. VRExplorer: An efficient view-region based autonomous exploration method in unknown environments for UAV[C]∥2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS). Piscataway: IEEE Press, 2024. |
| [124] | YAN P, JIA T, BAI C C. Searching and tracking an unknown number of targets: A learning-based method enhanced with maps merging[J]. Sensors, 2021, 21(4): 1076. |
| [125] | YAQOOT Y, MUSTAFA M A, SAUTENKOV O, et al. UAV-VLRR Vision-language informed nmpc for rapid response in UAV search and rescue[DB/OL]. arXiv Preprint: 2503.02465; 2025. |
| [126] | JI Y, ZHU Z, ZHAO Y, et al. Towards autonomous UAV visual object search in city space: Benchmark and agentic methodology[DB/OL]. arXiv Preprint: 2505.08765; 2025. |
| [127] | TIAN Y, LIN F, ZHANG X, et al. LogisticsVISTA: 3D terminal delivery services with UAVs, UGVs and USVs based on foundation models and scenarios engineering[C]∥2024 IEEE International Conference on Service Operations and Logistics, and Informatics (SOLI). Piscataway: IEEE Press, 2024. |
| [128] | 于彦鹏, 余墨多, 汤奇荣, 等. 面向城市应急物资配送的多无人机协同路径规划算法[J]. 控制与决策, 2025, 40(4): 1098-1106. |
| YU Y P, YU M D, TANG Q R, et al. Multi-UAV cooperative path planning algorithm for urban emergency logistics distribution [J]. Control and Decision, 2025, 40(4): 1098-1106 (in Chinese). | |
| [129] | 张启钱, 许卫卫, 张洪海, 等. 复杂低空物流无人机路径规划[J]. 北京航空航天大学学报, 2020, 46(7): 1275-1286. |
| ZHANG Q Q, XU W W, ZHANG H H, et al. Path planning for low-altitude logistics UAVs in complex environments [J]. Journal of Beijing University of Aeronautics and Astronautics, 2020, 46(7): 1275-1286 (in Chinese). | |
| [130] | YAO Y, LUO S, ZHAO H, et al. Can LLM substitute human labeling? A case study of fine-grained chinese address entity recognition dataset for UAV delivery[C]∥Companion Proceedings of the ACM Web Conference 2024.New York: ACM, 2024. |
| [131] | ZHOU B, XU H, SHEN S. Racer: Rapid collaborative exploration with a decentralized multi-UAV system[J]. IEEE Transactions on Robotics, 2023, 39(3): 1816-1835. |
| [132] | PAPYAN N, KULHANDJIAN M, KULHANDJIAN H, et al. AI-based drone assisted human rescue in disaster environments: Challenges and opportunities[J]. Pattern Recognition and Image Analysis, 2024, 34(1): 169-186. |
| [133] | PUEYO P, MONTIJANO E, MURILLO A C, et al. CLIPSwarm: Generating drone shows from text prompts with vision-language models[C]∥2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS). Piscataway: IEEE Press, 2024. |
| [134] | ZHANG T, TIAN Y, LIN F, et al. CoordField: Coordination field for agentic UAV task allocation in low-altitude urban scenarios[DB/OL]. arXiv Preprint: 2505.00091; 2025. |
| [135] | LIN F, ZHANG T, NI Q, et al. Talk less, fly lighter: Autonomous semantic compression for UAV swarm communication via LLMs[DB/OL]. arXiv Preprint: 2508.12043; 2025. |
| [136] | JI K, HU X, ZHANG X, et al. An LLM-based framework for human-swarm teaming cognition in disaster search and rescue[DB/OL]. arXiv Preprint: 2511.04042; 2025. |
| [137] | KRINNER M, ROMERO A, BAUERSFELD L, et al. MPCC++: Model predictive contouring control for time-optimal flight with safety constraints[DB/OL]. arXiv Preprint: 2403.17551; 2024. |
| [138] | BUI D N, KHUAT T H, PHUNG M D, et al. Model predictive control for optimal motion planning of unmanned aerial vehicles[C]∥2024 International Conference on Control, Robotics and Informatics (ICCRI). Piscataway: IEEE Press, 2024. |
| [139] | BOUCHEKIR R, GUZMAN M, COOK A, et al. Formal verification for safe AI-based flight planning for UAVs*[C]∥2023 53rd Annual IEEE/IFIP International Conference on Dependable Systems and Networks Workshops (DSN-W). Piscataway: IEEE Press, 2023. |
| [140] | TANG Y C, CHEN P Y, HO T Y. Defining and evaluating physical safety for large language models[DB/OL]. arXiv Preprint: 2411.02317; 2024. |
| [141] | SUN Y, CHEN Y, WU P, et al. DRL: Dynamic rebalance learning for adversarial robustness of UAV with long-tailed distribution[J]. Computer Communications, 2023, 205: 14-23. |
| [142] | REN Y, ZHU F, LU G, et al. Safety-assured high-speed navigation for MAVs[J]. Science Robotics, 2025, 10(98): eado6187. |
| [143] | BADAR A U R, MAHMOOD D, IQBAL A, et al. DeepSpoofNet: A framework for securing UAVs against GPS spoofing attacks[J]. PeerJ Computer Science, 2025, 11: e2714. |
| [144] | NVIDIA jetson AGX orin[EB/OL]. (2025-10-28)[2025-11-27]. . |
| [145] | Atlas 200I A2[EB/OL]. (2025-11-12)[2025-11-27]. . |
| [146] | RK3588[EB/OL]. (2025-08-08)[2025-11-27]. . |
| [147] | AR9481[EB/OL]. (2021-12-20)[2025-11-27]. . |
| [148] | MCENROE P, WANG S, LIYANAGE M. A survey on the convergence of edge computing and AI for UAVs: Opportunities and challenges[J]. IEEE Internet of Things Journal, 2022, 9(17): 15435-15459. |
| [149] | XU J, LI Z, CHEN W, et al. On-device language models: A comprehensive review[DB/OL]. arXiv Preprint: 2409.00088; 2024. |
| [150] | LIN J, TANG J, TANG H, et al. Awq: Activation-aware weight quantization for on-device llm compression and acceleration[J]. Proceedings of Machine Learning and Systems, 2024, 6: 87-100. |
| [151] | GU A, DAO T. Mamba: Linear-time sequence modeling with selective state spaces[DB/OL]. arXiv Preprint: 2312.00752; 2023. |
| [1] | . The Research on High-Precision Reconstruction of Sampling Areas for Exogenous Cameras in Mars Sampling Missions [J]. Acta Aeronautica et Astronautica Sinica, 0, (): 1-0. |
| [2] | . A Multi-source Autonomous Calibration Method for Asteroid Exploration [J]. Acta Aeronautica et Astronautica Sinica, 0, (): 1-0. |
| [3] | Lei ZHOU, Yanfeng GU, Tianzhu LIU. Aircraft fine-grained object detection algorithm in remote sensing images [J]. Acta Aeronautica et Astronautica Sinica, 2026, 47(10): 632578-632578. |
| [4] | . Physics-Guided Geometric Verification for UAV Visual Localization under Weak-Texture Conditions [J]. Acta Aeronautica et Astronautica Sinica, 0, (): 1-0. |
| [5] | Zhenyang HAO, Shang CAO, Fengting ZHANG, Lanlan HOU. Design of a hub-mounted active actuation system for helicopters [J]. Acta Aeronautica et Astronautica Sinica, 2026, 47(7): 432464-432464. |
| [6] | Yao ZHAO, Xi ZHANG, Di ZHOU, Yutang LI, Siyuan LI. Rapid reentry trajectory planning for hypersonic vehicles with proactive no-fly zone separation assurance [J]. Acta Aeronautica et Astronautica Sinica, 2026, 47(6): 332509-332509. |
| [7] | Zheng WANG, Shouzhi ZHAO, Haotian LI, Zheng SUN, Jing SHAO, Cheng HOU. Development status of ice-penetrating probes for deep space exploration [J]. Acta Aeronautica et Astronautica Sinica, 2026, 47(5): 332398-332398. |
| [8] | . Resilient Networking and Reconfiguration Method for Satellite Networks Oriented to Single Event Effects [J]. Acta Aeronautica et Astronautica Sinica, 0, (): 1-0. |
| [9] | Fei TAO, He ZHANG, Weiran LIU, Chenyuan ZHANG, Yupeng WEI, Li YI, Xiaofu ZOU. Theories and key technologies of digital experiment and validation for aerospace equipment [J]. Acta Aeronautica et Astronautica Sinica, 2025, 46(24): 432516-432516. |
| [10] | Liang CHEN, Fanxing MENG, Chengbo WANG, Yinxuan ZHANG, Linshu MENG. Development and application of digital twins technology in aircraft strength design [J]. Acta Aeronautica et Astronautica Sinica, 2025, 46(19): 532252-532252. |
| [11] | Tong LIU, Wenxiang ZHAO, Jinghua JI. Review of computational methods for electromagnetic vibration and noise in inverter-fed permanent magnet synchronous machines [J]. Acta Aeronautica et Astronautica Sinica, 2026, 47(1): 332127-332127. |
| [12] | Fan PU, Zhijie CHEN, Yang LIU, Xin GENG, Yongwen ZHU, Kejin REN. Air traffic management technologies for digital low-altitude integrated operations [J]. Acta Aeronautica et Astronautica Sinica, 2025, 46(11): 531331-531331. |
| [13] | Honglin LIU, Guan WANG, Shuaibin AN, Shaojie MA, Kai LIU. Online identification based strong adaptive control of hypersonic morphing vehicles [J]. Acta Aeronautica et Astronautica Sinica, 2025, 46(17): 331654-331654. |
| [14] | Shusheng CHEN, Muliang JIA, Jiahao LIN, Shiyi JIN, Zhenghong GAO, Yueqing WANG, Zhiqiang MA, Zheng LI, Chenlong DUAN, Jiawei LI. Empowering aircraft technology applications with generative models: Research progress and prospects [J]. Acta Aeronautica et Astronautica Sinica, 2025, 46(10): 631194-631194. |
| [15] | Jie LIN, Zhigong TANG, Weiqi QIAN, Yueqing WANG, Peng ZHANG, Weixia XU, Jie LIU. Research progress and prospects of aircraft aerodynamic design based on generative models [J]. Acta Aeronautica et Astronautica Sinica, 2025, 46(10): 631679-631679. |
| Viewed | ||||||
|
Full text |
|
|||||
|
Abstract |
|
|||||
Address: No.238, Baiyan Buiding, Beisihuan Zhonglu Road, Haidian District, Beijing, China
Postal code : 100083
E-mail:hkxb@buaa.edu.cn
Total visits: 6658907 Today visits: 1341All copyright © editorial office of Chinese Journal of Aeronautics
All copyright © editorial office of Chinese Journal of Aeronautics
Total visits: 6658907 Today visits: 1341
 CJA